MIT AI Training Method Aims to Broaden Climate Emulator Predictions
- Akanksha Gaur
- 749 reads
MIT researchers use optimized synthetic climate scenarios to train emulators with one Earth system simulation, targeting predictions beyond familiar emissions pathways.
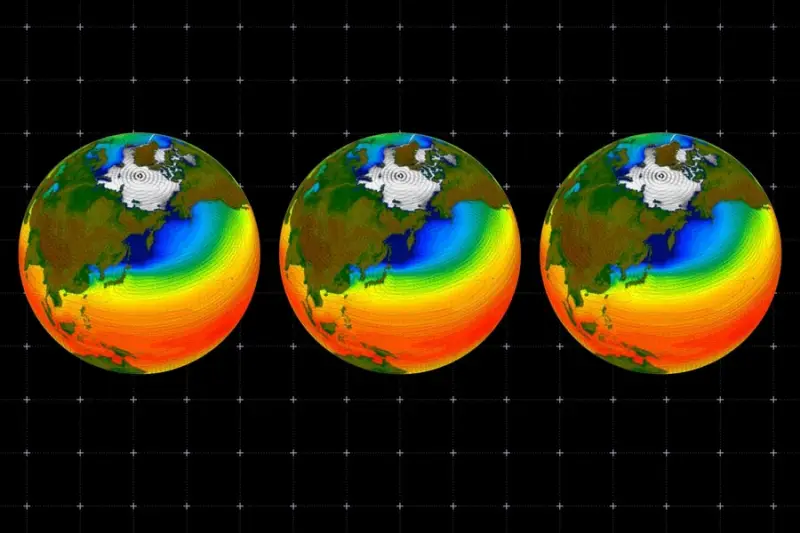
Climate emulators could become more useful when they can predict conditions beyond the emissions pathways used to train them. Researchers at the Massachusetts Institute of Technology (MIT) describe a method that builds optimized synthetic training scenarios to help an artificial intelligence model generalize from a smaller set of costly climate simulations.
Why training data limits prediction
Climate emulators are AI systems designed to approximate the output of large Earth System Models (ESMs). ESMs represent physical processes in the planet’s climate system and are used to project changes such as temperature, precipitation and sea level under different greenhouse gas emissions. Running an ESM on a supercomputer can take several months for a single scenario, according to the researchers’ account.

That computational cost puts a practical limit on how many scenarios can be simulated for training. A conventional emulator dataset may contain six to eight plausible emissions scenarios. Those examples can teach the model how climate variables respond along the trends represented in the data, but they may leave it poorly prepared for combinations or trajectories it has not seen.
That’s the central engineering constraint: an emulator runs more cheaply than a full ESM, but its usefulness depends on the coverage and quality of its training examples. A model trained on a narrow range of inputs may produce less reliable predictions when asked to handle a substantially different emissions pattern. Adding more examples through conventional simulation can help, but each additional ESM run carries a high computational cost.
Synthetic scenarios target the emulator’s errors
The MIT approach uses an optimization algorithm to generate artificial climate scenarios for training. It begins with a randomly selected scenario produced by a lower-order climate model. Researchers then estimate the emulator’s prediction error by comparing its output with the lower-order model’s result. The algorithm adjusts the synthetic training scenarios to reduce that error.
The method therefore uses the emulator’s own weak points to shape the training data. Instead of relying only on a fixed set of smooth, plausible emissions pathways, it constructs examples intended to expose where predictions need improvement. The researchers say one simulation can provide the training data for this process, in contrast with the several costly ESM simulations required by the conventional approach they describe.

A key feature is the inclusion of rapid fluctuations in carbon dioxide and methane emissions. Typical datasets tend to follow smoother patterns that reflect plausible emissions trends. The synthetic examples deliberately vary those emissions more quickly, giving the AI model exposure to changing inputs that may not appear in its original training set.
That difference matters because a climate emulator must learn relationships between emissions and climate outcomes, rather than simply reproduce a familiar trajectory. When training examples cover a broader range of input behavior, the model may be better equipped to estimate outcomes under unfamiliar conditions. The approach is designed to improve that coverage without requiring a large collection of expensive full-model simulations.
A test beyond familiar emissions pathways
The researchers report that the trained emulator could predict a scenario absent from its training dataset: regional pollution control in which one pollutant decreases while emissions of another increase. This example tests whether the model can handle pollutants moving in different directions, rather than assuming that all emissions rise or fall together.
For climate modeling teams, the practical appeal is a possible reduction in the number of high-cost simulations needed to prepare an emulator for varied scenarios. A smaller simulation burden could make it easier to explore questions that would otherwise require additional ESM runs. The method also points to a different role for synthetic data: it can be shaped around prediction errors, not just used to fill out a dataset with more examples of familiar behavior.
There are limits to what the reported result establishes. The account gives no numerical accuracy measurements, runtime comparisons or details about how performance changes across different climate variables. It also does not say how the method performs across a broader set of unfamiliar scenarios. Those details would help teams judge how much confidence to place in predictions and where full ESM simulations remain necessary.
For now, the main takeaway is methodological: training data can be optimized to challenge an emulator with changing emissions patterns, while using fewer costly simulations than the conventional approach described by the MIT researchers. The next practical question is how consistently that strategy improves predictions across different scenarios and climate outputs.


